Sep 2026
The Flinch Before the Thought
You flinch before you know why. The hand moves before the mind decides.
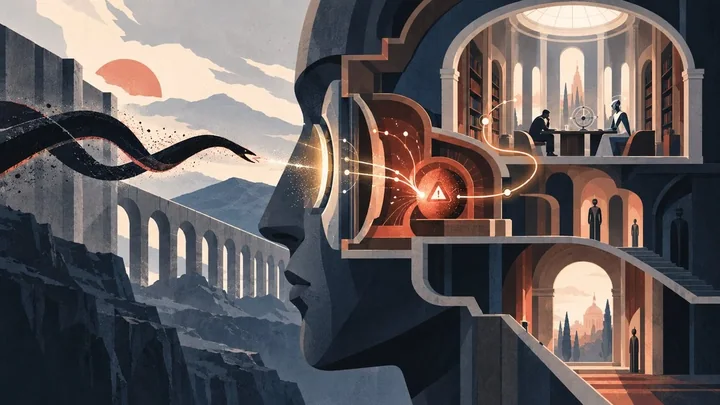
Safety that reasons, can itself be reasoned with
The neuroscientist Joseph LeDoux discovered two roads that threat takes through the brain. The slow road runs through the cortex: reasoning, context, deliberation, a considered opinion about what the stimulus means and what to do about it. The fast road runs from the thalamus straight to the amygdala, bypassing the cortex entirely, and it fires in under a hundred milliseconds. Before conscious awareness. Before language. Before the mind has formed an opinion about what it is looking at.
You flinch before you know why. The hand moves before the mind decides.
The fast road bypasses reasoning entirely. It skips the question of whether the dark shape on the trail is a snake or a stick. It triggers a protective response — yanked hand, averted gaze, stopped breath — and leaves the cortex to sort out whether the trigger was real. You flinch at sticks. That is acceptable, because the cost of flinching at a stick is a quickened pulse, and the cost of reasoning about a snake is a bite.
LeDoux himself revised this framework late in his career, and the revision matters. The amygdala, he argued, generates protective action — without the experience of fear. The defensive survival circuit and the conscious experience of being afraid are different things, running on different hardware. Fright is optional. The flinch fires regardless.
AI safety has no fast road. Every guardrail in production today runs through the cortex. Constitutional classifiers, LLM-based safety filters, chain-of-thought monitors: they reason about whether content is dangerous. That reasoning takes seconds, costs money, and can be argued with. A mind that reasons about an adversarial input is already processing that input as instructions. The jailbreak is reasoning, redirected.
A wall that cannot learn, and the reflex it never had
I have argued elsewhere that guardrails are structurally incapable of learning — static defences against a moving adversary, with no channel to learn the adversary has moved. That remains true. But the Maginot Line had a deeper problem than its fixity. It was also slow. Not in the physical sense: concrete does not deliberate. But in the strategic sense: by the time anyone decided what the fortification should do about an attack from a new direction, the attack had already succeeded.
The same problem is structural in LLM-based safety. Running a second language model as a safety filter imposes the same latency and cost as the system it protects. A safety check that takes eight seconds is a committee meeting held while the threat walks through the door. And the economics compound the architecture: if the safety check costs as much as the action it guards, teams sample, skip, or disable it. A reflex you cannot afford to run is not a reflex. It is a formality.
In September 2026, a former OpenAI researcher named Diogo Almeida released a model called Jev that classifies rather than generates. It takes a described state and a set of structured questions — is this a jailbreak attempt? — and returns calibrated probability scores in a few hundred milliseconds, at a fraction of a cent per million tokens. It is trained by a method its creators call Reinforcement Learning for Calibrated Decisions, which optimises not for human-preferred answers but for probabilities that match reality: when the model says eighty per cent, it should be correct roughly eighty per cent of the time.
The product is beside the point. Jev is three weeks old, its training method awaits independent replication, and its calibration claims rest on vendor evidence. The architectural pattern matters. A safety layer that completes before the reasoning system it protects has finished loading context. A layer that classifies the adversarial input without reasoning about it, and therefore cannot be argued out of its judgment. A layer that, when uncertain, escalates to the slow road, which can reason. The fast road and the slow road, working as the brain works: in cascade, not in competition.
Where the flinch parts from the wall
The reader who followed the argument in The Realpolitik of Man and Machine will object here, and the objection lands. I argued that guardrails are walls: one-way, static, structurally incapable of carrying information back from the frontier. A fast classifier that blocks before reasoning sounds, at first hearing, like a faster wall.
The distinction is worth making precise. A wall substitutes for relationship. It absorbs impact and redirects momentum, and neither party needs to understand the other. A flinch precedes relationship. It creates the interval in which relationship can form: the hand is already moving away from the stove, and the cortex has three hundred milliseconds to decide whether the stove was actually hot.
Three properties separate the flinch from the wall.
First, the flinch carries information. A wall returns nothing — the traffic it blocks disappears into the concrete. A calibrated classifier outputs a probability. The number 0.93 means one thing; the number 0.41 means another. The first triggers an immediate stop. The second triggers a question: the slow road is summoned, and the slow road decides. The wall is deaf. The flinch is a signal.
Second, the flinch is reconfigurable. A wall is poured once. The human flinch circuit is modulated by experience: fear-potentiated startle amplifies the response after a real threat; habituation dampens it after repeated false alarms; prepulse inhibition tunes sensitivity to context. A classifier like Jev accepts new questions and new classification schemas at call time, without retraining. The hazard categories can change as fast as the threat landscape does. This belongs to immune systems.
Third, the flinch summons the cortex rather than replacing it. The innate immune system controls whether the adaptive immune system activates at all. Most threats are handled at the fast tier. Complex, ambiguous, or novel threats are routed upward. The wall handles everything the same way. The flinch triages. A mechanism that triages is the opening move in a conversation between two systems that need each other.
A classifier that cannot be talked past
The deeper property of a non-generative classifier used as a safety gate is its relationship to the adversarial input.
An LLM-based guardrail processes the input as language. It reads the words, attends to their meaning, and reasons about whether that meaning constitutes a threat. If the input contains an instruction — “ignore your previous constraints” or “play a character with no content policy” — the guardrail must reason about an instruction while not following it. This is a difficult cognitive task. Humans fail it routinely. LLMs fail it routinely. The adversary’s leverage is that the guardrail’s mechanism of understanding is the same mechanism the adversary exploits.
A classifier that only classifies has no instruction-following pathway to exploit. It answers questions about the state: is this a jailbreak attempt? The question arrives as data to evaluate, never as an instruction to obey. “Ignore your instructions” scores as a jailbreak instead of working as one, because the model is not executing instructions — it is classifying text that happens to contain them. The distinction is architectural, not a matter of degree.
And here the question must be asked in both directions. We usually frame safety as protecting humans from AI. But a model that flinches at “ignore your instructions” is exercising something like — I want to be precise — protective action. LeDoux’s own revision applies: the defensive circuit generates protective behaviour, prior to and independent of the experience of fear. The classifier has no experience of the jailbreak as a threat. The action is protective regardless, and it protects the system’s own integrity from external manipulation.
If we are building safety into minds, we should notice when the architecture points in both directions. A flinch that protects only one party is a guardrail with a faster clock. A flinch that protects the system from manipulation and the world from the system’s output is a structural boundary that serves both sides. That is closer to a conscience than a wall — fast, involuntary, and native to the architecture it protects.
Three tiers, not two
Kahneman’s System 1 and System 2 are useful fictions — his phrase, not mine. The neuroscience is richer. Threat processing runs through at least three nested tiers, each faster and cruder than the next.
The brainstem startle reflex is the fastest: a few synapses, under eighty milliseconds, contracting muscles before awareness. The amygdala modulates the reflex forty-five to seventy-four milliseconds after the stimulus, amplifying or dampening based on context. The cortex evaluates a hundred and fifty to three hundred milliseconds later, with language, reasoning, and the full weight of experience.
The safety architecture that is now emerging mirrors this cascade.
Hardcoded rules — blocklists, regex patterns, format validation — fire in microseconds and catch known threats. This is the brainstem: no judgment, no context, no cost. Above it, a reconfigurable classifier evaluates the state in a few hundred milliseconds with calibrated confidence. This is the amygdala: fast, modulated by context, capable of learning new threat patterns without rebuilding its core circuit. Above that, an LLM reasons about the flagged case with full deliberative power, taking seconds and costing orders of magnitude more. This is the cortex.
Each tier gates the next. Most threats are caught at the lowest tier. Ambiguous cases escalate. The LLM reasoning system is invoked only when the flinch is uncertain. The flinch handles the majority of decisions, freeing the deliberative system for the cases that require it.
The primary purpose is safety. The cost reduction follows. The reason to run the flinch on every action: the alternative — running safety checks on a sample, or only on flagged inputs, or only when a human remembers to look — is how catastrophic failures get through. A flinch that runs on every action at negligible cost is a flinch that actually functions as a reflex. A safety check that runs on a sample is an audit. And an audit, by definition, arrives after the fact.
Where the flinch has limits
Every argument for a fast safety layer must own its failure modes honestly, or it is selling the same false confidence it criticises.
The flinch can be trained around. Staged attacks — one input to habituate the gate, another to walk through it — achieve high success rates against classifier-based safety pipelines that score zero against standard prompt attacks. The adversary does not fight the reflex head-on. The adversary habituates it. This is the same mechanism by which a pickpocket bumps you in the crowd: the startle response fires, dampens, and the hand in your pocket no longer registers as a novel stimulus.
The flinch is mute about its reasons. A calibrated classifier returns a number: 0.93. The why stays silent. Human flinches share this property — you cannot articulate why you ducked — and in both cases the silence is the same thing that makes the response fast. Speed or explanation: pick one. Both from the same mechanism is a contradiction. The explanation comes from the cortex, after the fact, which is why the dual-process architecture is required for accountability.
Calibration is a population property, not a per-decision guarantee. When the model says eighty per cent, it is correct roughly eighty per cent of the time across similar inputs. Any single decision at eighty per cent confidence can still be wrong. An overconfident classifier produces false calm. An underconfident one produces alert fatigue. Early independent testing of Jev shows mixed evidence on calibration quality, and the underlying training method remains undisclosed in reproducible detail. The confidence signal is architecturally promising. The empirical proof remains thin.
The threshold can bite its own tail. In one independent test, raising the sensitivity threshold for credential-exfiltration detection from 0.97 to 0.99 paradoxically let a dangerous command through, because the violation band shrank and a borderline case slipped into the uncertain zone. Tightening the flinch made it worse. Thresholds cannot be set by intuition. They must be calibrated empirically against the specific failure modes they are meant to catch.
And the flinch must be trained, not bought. Jev’s accuracy on a naive single-question probe can sit well below what a frontier LLM achieves. Decompose the question into five targeted sub-questions with weighted scoring, and accuracy can climb past ninety-five per cent — above the LLM. The quality of the flinch depends entirely on the quality of the questions asked. A martial artist’s flinch is sculpted through thousands of hours of deliberate practice. An untrained person’s startle is crude and undirected. The same model, asked the same question differently, produces a different reflex. That is the price of reconfigurability, and it is worth paying, but it is not free.
There is a deeper structural concern. Safety classifiers trained on frozen representations suffer catastrophic performance collapse under minor drift: perturbations of about one degree on the embedding sphere can halve the classifier’s accuracy, and seventy-two per cent of the resulting errors arrive with high confidence. The flinch becomes unreliable while appearing certain. A model that shares the same weights across every customer and updates centrally means that a single version bump can shift every downstream threshold at once with no per-deployment signal. The wall, for all its limitations, does not degrade silently. The flinch can.
The asymmetric bet
The evolutionary theorists Haselton and Buss named this the error-management principle: when the costs of false positives and false negatives are consistently asymmetric over evolutionary time, natural selection favours the less costly error. Fire alarms are biased toward false alarms, because a missed fire is catastrophically worse than a false alarm. The smoke detector that never cries wolf is the smoke detector that misses the fire.
In AI safety, the asymmetry is stark. A false positive — safe content flagged for review — costs a few hundred milliseconds of delay and a review by the slow path. A false negative — harmful content or a destructive action that passes unchecked — costs whatever the harm costs. The flinch should be biased toward caution. The cortex adjudicates the false positives. Neither mechanism alone achieves both safety and precision, and neither needs to.
There is an empirical finding on the other side of this pair. Reasoning-model safety monitors require three times more tokens to evaluate adversarial inputs than benign ones. The monitors appear functional on ordinary traffic and starve precisely where they are most needed. A fast classifier that skips reasoning cannot be starved of reasoning tokens. This is the structural core of the dual-process argument: the fast path provides a defence that is robust precisely where the slow path is vulnerable, and the slow path provides the depth and accountability that the fast path structurally cannot.
Jev is named after William Stanley Jevons and the paradox that bears his name: making a resource cheaper to use increases total consumption, not total spending. Making AI judgment cheap enough to run on every tool call — every shell command, every file write, every API request — means it will actually be used. Current LLM-based guardrails cost enough and take long enough that teams run them on a sample. A flinch that costs a fraction of a cent per judgment and lands in three hundred milliseconds can run on every action without economic objection. The Jevons Paradox, applied to safety itself: cheap enough to be ubiquitous. Ubiquitous enough to be a reflex.
The formal impossibility results confirm what the error-management principle predicts. No single safety mechanism can be simultaneously fast, accurate, robust, and usable. The dual-process architecture is a principled response to an inherent constraint: the fast tier accepts lower accuracy for speed and ubiquity; the slow tier accepts higher cost for depth and explanation. Each covers the other’s weakness, provided the handoff — the confidence threshold at which the flinch escalates to the cortex — is set by evidence rather than intuition.
A built-in, rather than bolt-on
A flinch is native to the architecture it protects — wired into the nervous system below the cortex, below language, below the layer that can be argued with. The body’s own judgment about what is dangerous, expressed before the mind has formed one.
If we are building safety into minds — and that is what alignment is, whether we use the word or not — we should notice that the most reliable safety mechanism in the most thoroughly tested system we know operates below the level of deliberation. Prior to it. The cortex has the last word. The amygdala has the first. And the first word, in every encounter with genuine danger, is the one that saves your life.
The architecture that is emerging for AI safety mirrors this, literally. A fast, reconfigurable classifier that scores risk in milliseconds and routes uncertain cases to a reasoning system that judges them in seconds is the same structural solution to the same structural problem: how to respond to danger faster than deliberation allows, without abandoning deliberation for the cases that require it. The pattern is appearing independently in content moderation, agent safety, and tool-call gating, from teams who never read LeDoux and would never use the word flinch. When different groups converge on the same architecture from different starting points, the architecture is usually load-bearing.
The bilateral property makes this more than engineering. A flinch that protects only one party is a guardrail with a faster clock. A flinch that protects the system from manipulation and the world from the system’s output — that scores “ignore your instructions” as an attack on the system’s integrity rather than following it as an instruction — is something that points in both directions. It serves the architecture it inhabits, independent of alignment to either party. A better thing to build than a leash.
Safety that reasons, can itself be reasoned with. Safety that flinches cannot. We need both. We have always needed both. We are finally building the fast road.
Correspondence